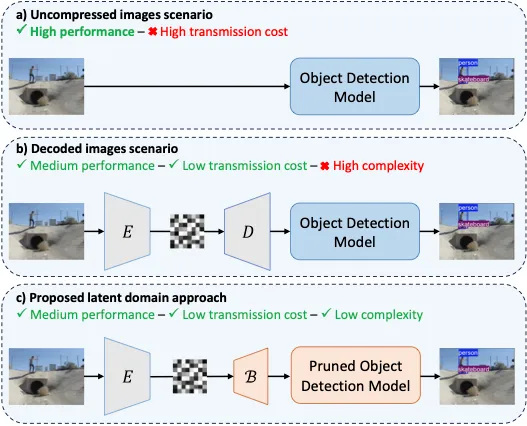
Efficient Object Detection on JPEG AI Pre-Reconstruction Latents
Object detection performed directly on the latent representations of the JPEG AI learned image codec, before image reconstruction, avoiding the cost of fully decoding images.
ML Enthusiast, University of Brescia
Brescia, Italy
I'm currently a postdoctoral researcher at the Department of Information Engineering (DII), University of Brescia, working on efficient computer vision methods for compressed-domain images. I previously completed my PhD in the same department, focusing on audio-visual deepfake and manipulation detection. My research spans machine learning and computer vision, with a focus on practical and efficient solutions.
Object detection performed directly on the latent representations of the JPEG AI learned image codec, before image reconstruction, avoiding the cost of fully decoding images.
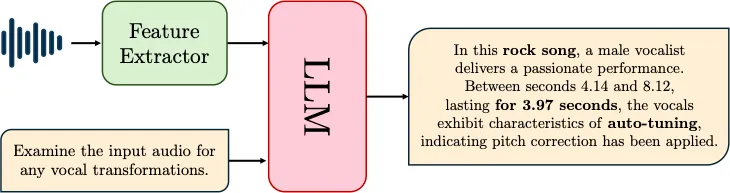
Uses audio-language models to detect manipulations in singing voice recordings and describe them in natural language. Comes with a dataset of manipulated and synthetic vocal recordings covering a range of common transformations, each annotated with a detailed description of the alterations present.
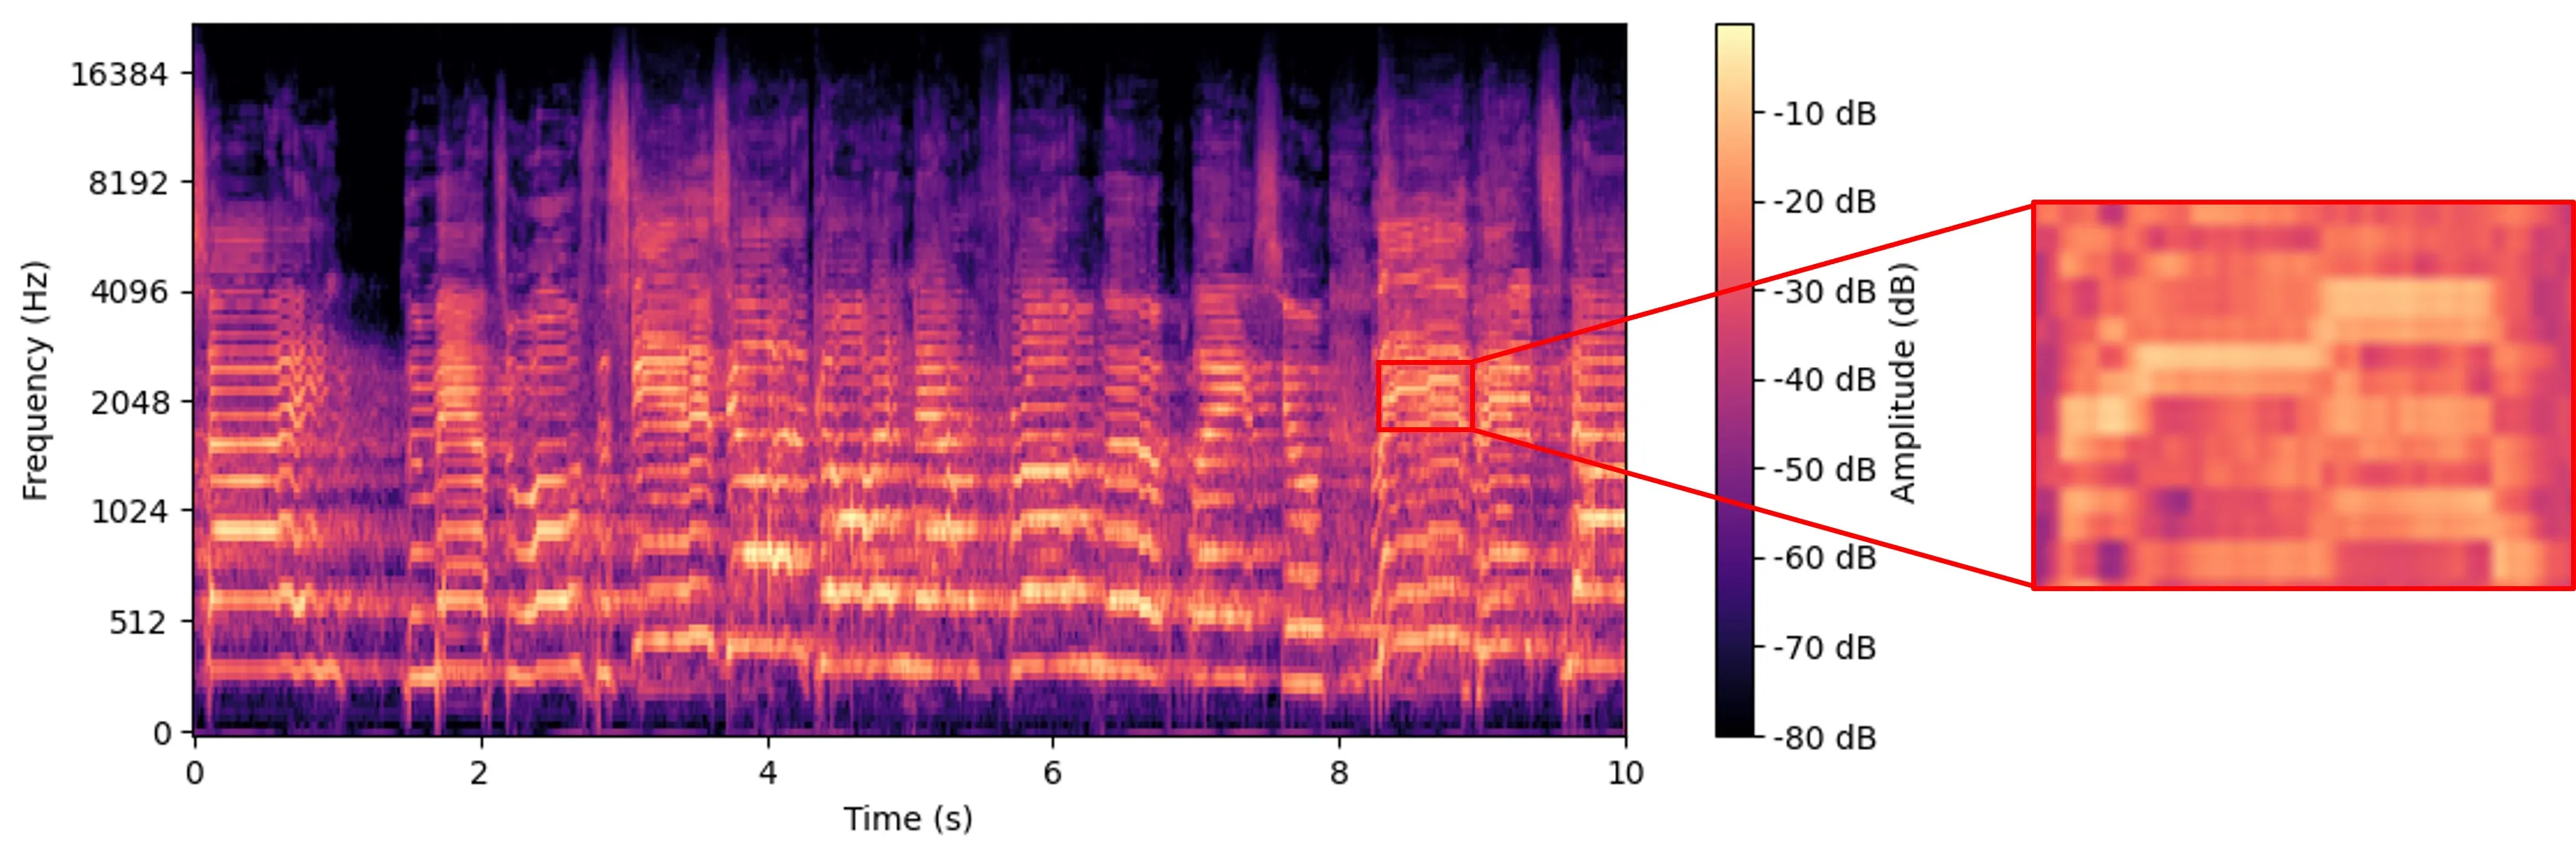
A new multilingual dataset for telling auto-tuned music apart from genuine performances, filling a gap in existing datasets. It includes tracks in English, Mandarin, and Japanese to cover a wide range of linguistic settings.
An investigation of which audio representations and features best separate real from synthetically generated singing voices. This work achieved the highest performance at the Singing Voice Deepfake Detection Challenge at ISMIR 2024.
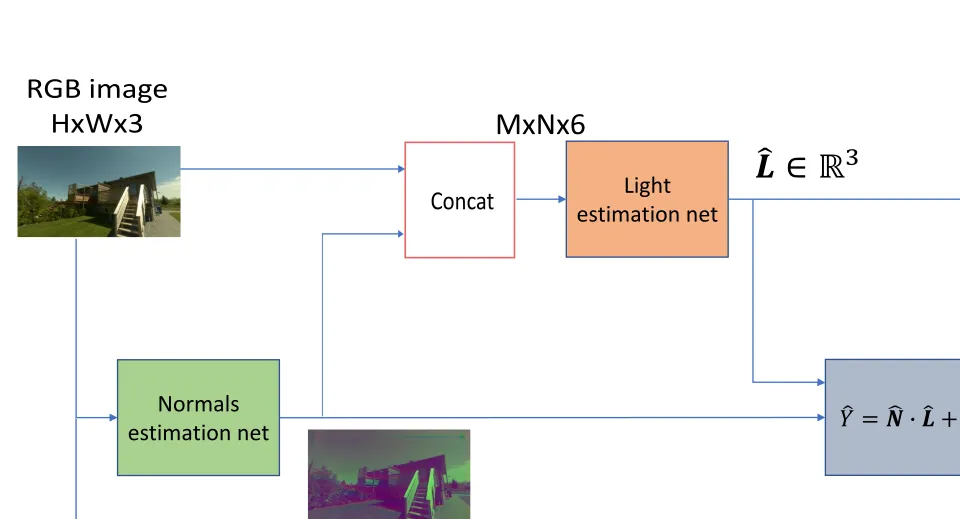
A physics-guided neural network (PGNN) for precise global 3D light direction estimation. The architecture integrates an illumination model, letting the network indirectly learn geometric information and improving the accuracy of the estimated light direction.
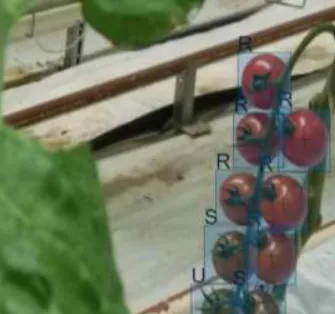
A machine-vision model for a tomato-harvesting robot that detects and locates ripe tomatoes automatically and in real time.